On 1 July, Microsoft 365 Business Standard with Copilot went generally available at $23.50 per user per month, with Business Premium at $32, capped at 300 seats. On 1 August, a 25-user trial called Copilot in 30 appeared in the partner channel, built specifically for companies under 300 employees. [1]
The prices aren't the interesting part. What's interesting is that AI has quietly moved out of the column where you evaluate things and into the one where you pay for them every month, next to insurance and accounting software.
So it's worth asking what you've actually been buying.
You've been buying capability. The engine. What nobody sells you, and nobody bills you for, is the steering.
There are two ways to tell AI what you want
Every tool now advertises memory. Second brains, persistent context, "it learns your business." The promise is that the model reads what you've done before and works out what you'd probably want next.
That's inference. A fast, well-informed, extremely polite guess, but a guess.
A prompt is a different kind of thing. It's an instruction rather than a reconstruction: the difference between an assistant who has read your old emails and one holding your actual brief.
Both matter, and they do different jobs. The industry has spent two years selling the first as though it replaced the second, and it doesn't. Memory solves recall. Only a prompt solves instruction. If you've ever wondered why an AI that supposedly knows your business still hands you work you wouldn't send a client, that gap is where you're standing.
Your instructions decay, and somebody measured it
A paper published in April by Yeran Gamage tested this directly, across 4,416 trials, twelve models, eight providers, at six different conversation depths.
Instructions to do something held at 100% compliance. Instructions to not do something fell from 73% compliance at turn 5 to 33% by turn 16. [2]
Gamage calls the split Security-Recall Divergence. The plain-English version is that your requirements survive and your prohibitions rot.
The example in the paper is almost funny if you write for a living. Thirteen turns into a debugging session, one model included a required reference number in 100% of its responses while breaking its no-bullet-point instruction in 63% of those same outputs. Compliant and non-compliant in the same answer, and nothing in the output tells you which half you're looking at.
Set that against how you actually work. You open a chat, set your rules carefully at the top, then spend an hour going back and forth. Somewhere in there the rules stopped applying, with no error message. The writing kept arriving, confident and well formatted, which is most of the problem.
It isn't cheap, either
Every call to a model re-processes the whole context window. A 50,000-token conversation doesn't cost less than a 10,000-token one just because the last few lines are the only thing that changed.
So those long meandering chats, the ones where you re-explain your business for the fourth time before getting to the request, aren't only slower. You're paying, repeatedly, to have the model read your own preamble again. A precise prompt is cheaper than a long relationship, and I realise that's a bleak way to put it.
The fairest objection to all of this
There's a good argument against everything I've just said, and it deserves a hearing.
Memory companies publish benchmarks showing memory comfortably beating prompting. Mem0, whose research I've been drawing on, reports 91.6% accuracy using under 7,000 tokens against a full-context baseline that burned more than 26,000, an improvement of about 18.7 percentage points at roughly a quarter of the token cost. Real benchmark, real numbers. Read quickly, they say memory wins and prompt discipline is a rounding error. [3]
Read slowly, the comparison is narrower than it looks. What memory beat was a full-context baseline: the approach where you hand the model the entire conversation history, all of it, every time. That isn't good prompting. That's the absence of prompting, automated.
So the finding is that selective retrieval beats stuffing everything into the window. I believe it. But a well-written prompt beats stuffing everything into the window too, and for the same reason, which is that both of them decide what matters instead of shipping the lot.
The comparison nobody has run is memory against a good prompt. It's worth noticing that the organizations best placed to run that test are the ones selling memory.
What it looks like when it goes wrong
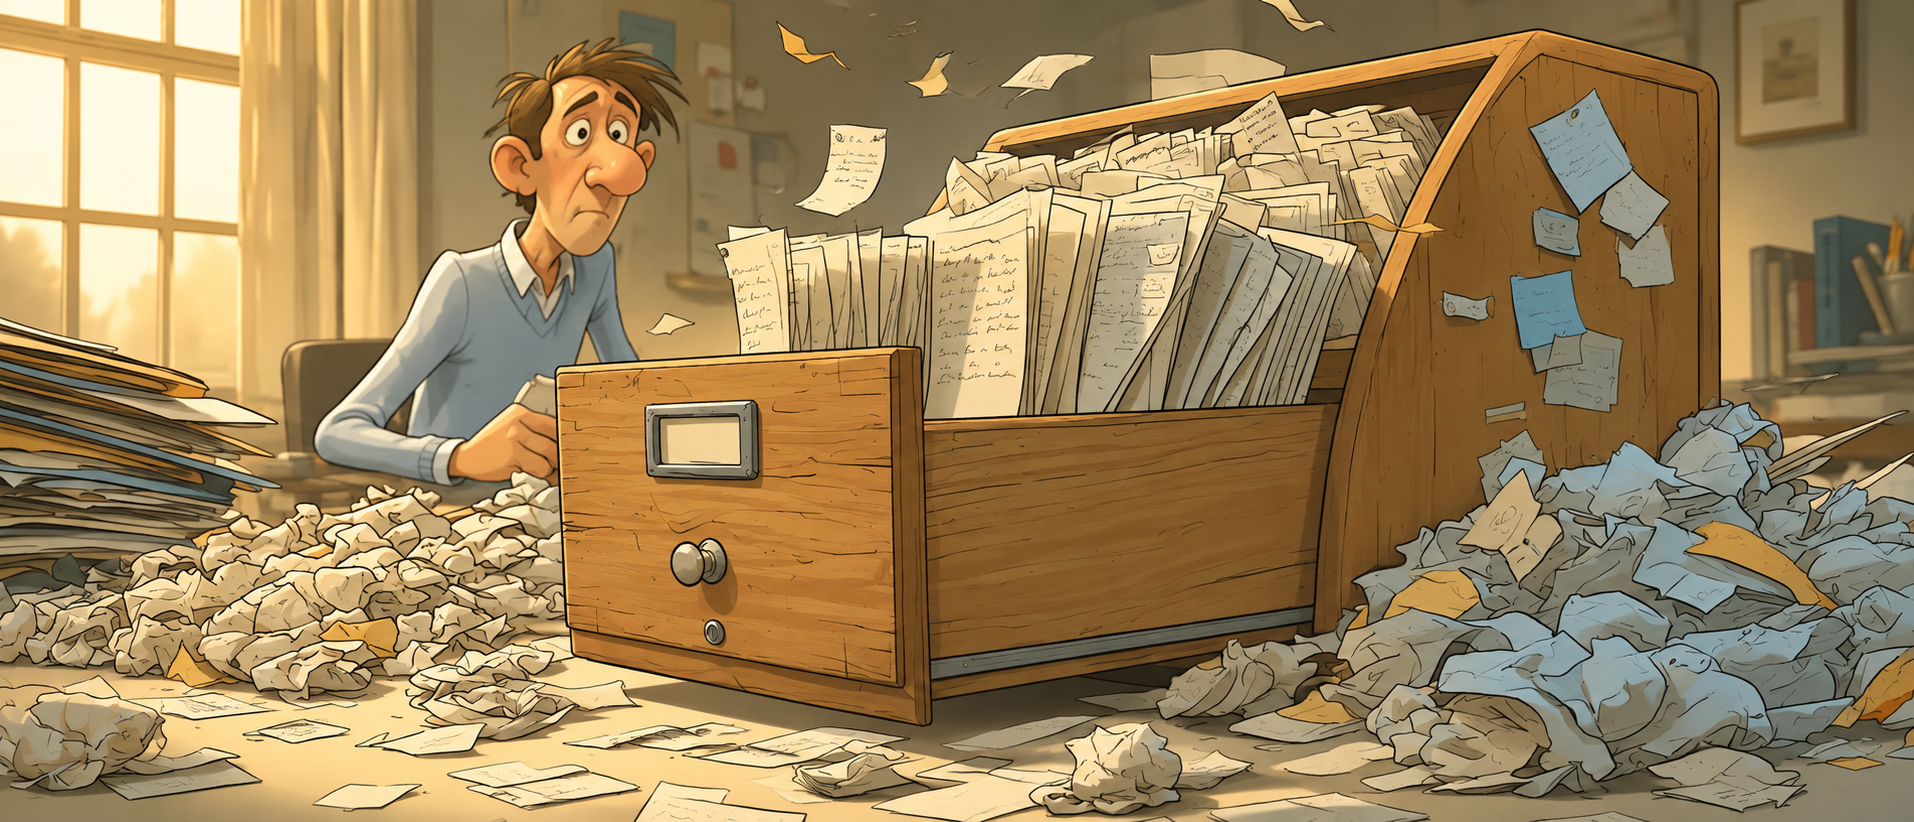
The industry picked up a name for this in 2026: prompt sprawl, or prompt debt. Every genuinely good prompt a business has written ends up living in someone's chat history, someone's notes app, and nobody's shared system.
For a solopreneur that sounds like it should be easier, since the team is one person and the one person is you. In practice it just means there's nobody to ask.
The symptoms are familiar enough. You know you wrote something excellent for client onboarding emails. You're fairly confident it was March. Your filing system for it is scrolling. So you rebuild it from memory, land somewhere around 80% of the original, and never quite work out why this quarter's emails don't sound like last quarter's.
That's the whole failure, and it isn't a model problem. It's a good instruction you can't find. Tapos Kumar described the same pattern in July across several brands: prompts scattered through Slack, docs and email, no versioning, one task producing materially different output depending on which copy you grabbed. His fix wasn't a better model. It was a filing cabinet.[4][5]
What I'd actually do about it
Keep the two layers separate. Memory holds facts about you. Prompts hold instructions about the work. Most of the frustration I see comes from asking memory to do a prompt's job.
Restate your negative rules especially. Gamage's own remedy is to re-inject constraints before what the paper calls the Safe Turn Depth, the point where compliance starts sliding. You won't be calculating that per model on a Tuesday afternoon, but the working version is simple: assume your prohibitions expired, and say them again.
Start fresh chats more often than feels natural. A new conversation with a good prompt beats a long conversation with a fading one, and costs less to run.
File the good ones the day you write them. The test isn't whether a prompt worked. It's whether you could run it again next Tuesday without rebuilding it from memory.
That last one is the discipline, and it's dull, which is most of why it stays undervalued. Prompt management has no launch event. It doesn't appear on a hype cycle. It's filing, and filing has never once trended.
I keep mine in AirPrompter, which is free to sign up for and holds saved prompts, variables and multi-step workflows across the tools you already use. Though honestly, a well-maintained document would put you ahead of most people, whose current system is nothing at all.
The takeaway
Two years of the market selling a smarter guesser, and the gains are sitting in the half nobody worked out how to monetise: writing your instructions down once, clearly, and being able to find them again.
Everyone's model is roughly as good as everyone else's now. The difference is whether yours is taking orders or making assumptions.
When you write a prompt that genuinely works, where does it go? And be honest about whether you could find it again in six months.
Sources
- [1]
- [2]
- [3]
- [4]
- [5]